AI agents
Why AI agents fail in production: it is not the model
Probabilistic reasoning. Deterministic control.
In brief
Most AI agents fail in production for reasons that have nothing to do with the model being wrong. The model reasons well, and the system around it does not hold. A retry duplicates a payment, the agent acts on stale state, a tool runs with more authority than the user has, or nobody can reconstruct what happened. These are distributed systems problems, and they have distributed systems answers.
On this page
- 01Production is not a prompt
- 02Five reasons AI agents fail after the demo
- 03This brought me back to CAP
- 04Why an AI agent hits the same fork
- 05The failure that is worse than a timeout
- 06CARE: a design lens for production agents
- 07Authority has to rise with capability
- 08What we see in production
- 09Five questions before an agent touches real operations
- Frequently asked questions
01Production is not a prompt
The most expensive AI failures I keep running into have nothing to do with the model being wrong. The model was right. The system around it was not. That gap is where most enterprise agent projects quietly die: after the demo, before the rollout.
In a demo, an agent gets a request, reasons about it, calls a tool and produces an impressive result. In production, the same agent has to operate inside a real business: customers, permissions, legacy systems, human approvals, network failures, retries, timeouts, regulatory controls and audit requirements. And one thing the demo never had: consequences.
If a chatbot repeats an answer, it is mildly annoying. If an agent sends a customer communication twice, approves a workflow twice or executes a transaction twice, that is a production incident, a compliance conversation and sometimes a refund.
There is a second complication. A probabilistic decision maker now sits inside the execution path. The network can fail. The API can time out. State can go stale. And the agent can make a different decision when the workflow is retried.
So the real production question is no longer how to make the model more accurate. It is how to let AI reason probabilistically while business execution stays reliable, authorized and explainable. This is the moment agentic AI stops being an AI problem and becomes a systems architecture problem.
02Five reasons AI agents fail after the demo
These are the failure modes I see over and over when AI moves from prototype to production.
- 01
Confusing model intelligence with system reliability.
A model can reason perfectly while the workflow still fails. An API times out, state goes stale, a retry duplicates an operation. Reliability is a property of the whole system, never of the model alone.
- 02
Letting the agent become the source of truth.
Agent memory and conversation history are useful context. They should never decide whether a consequential business operation actually happened. Authoritative state belongs in the systems that own it.
- 03
Granting tools without defining authority.
Being able to call a tool is not permission to execute everything that tool exposes. Tool access, user authority and business policy are three different concerns, and most implementations collapse them into one.
- 04
Designing the happy path, not the recovery path.
The interesting question is not whether the agent can finish the workflow. It is what happens when it gets 70% of the way through and something fails.
- 05
Observing infrastructure, but not decisions.
HTTP 200 tells you almost nothing. For consequential AI you need to know what the agent understood, which tool it picked, which policy applied, whose authority it acted under, whether a human approved and what actually changed.
If you recognize three or more of these in your own stack, the model is not your bottleneck.
03This brought me back to CAP
None of these are new engineering problems. Distributed systems engineers have wrestled with partial failure, concurrency, retries, consistency and recovery for decades. What is new is that we have inserted probabilistic reasoning into the execution path. Which brought me back to the CAP theorem.
Picture your system running in two data centers. The link between them drops. Each side is still healthy and still serving traffic, but neither can see the other. That is a partition. Now a write lands on one side and a read for the same record lands on the other. You have two options and no third. Refuse the read until the link is restored, which protects correctness and gives up availability. Or answer from local state, knowing it may be stale, which stays responsive and gives up consistency.
The "pick two of three" triangle is memorable and slightly wrong. Eric Brewer, who stated the conjecture, wrote twelve years later that the "2 of 3" framing oversimplified the tensions and that partitions are rare. He added that the choice between consistency and availability can be made many times within the same system at very fine granularity. That last point is the useful one. Partition tolerance is not optional, because networks fail. So the real decision is consistency or availability, and it is made per operation, not once for the whole system. Your product catalog can serve slightly stale data. Your payment ledger cannot. Same system, opposite choices, both correct.
04Why an AI agent hits the same fork
Your agent fires a payment operation and the call times out. The agent genuinely does not know whether the payment committed. It is, in the most literal sense, partitioned from the truth. It can stop and wait for authoritative confirmation, which is correct but stalls the workflow. Or it can proceed on its best guess, which is responsive but may pay a supplier twice.
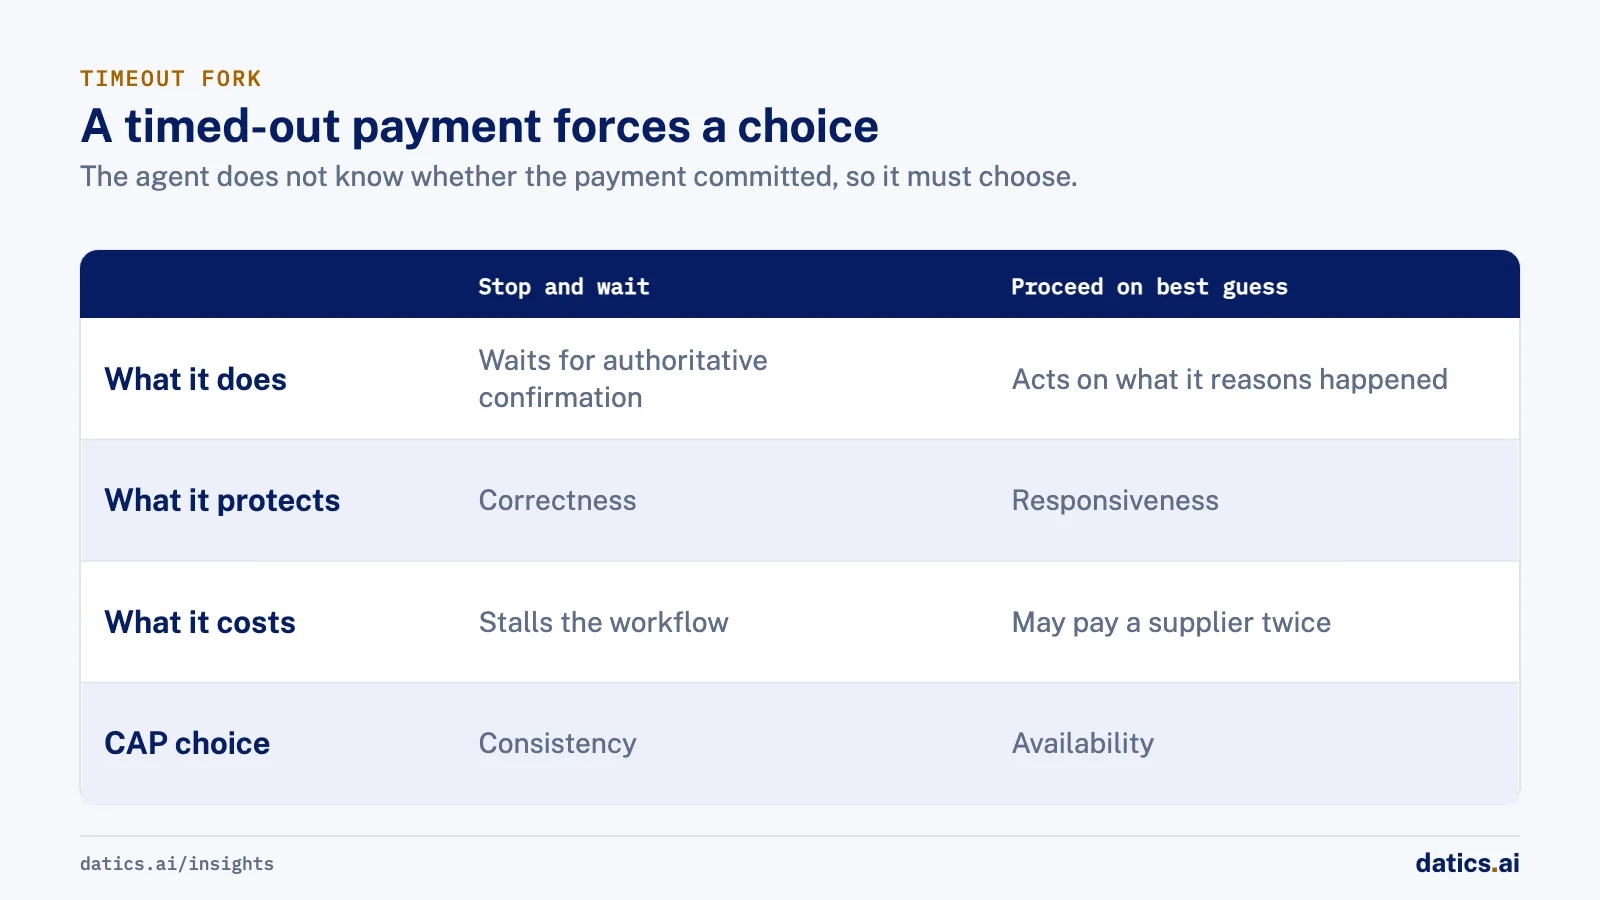
Most agent implementations never make this choice deliberately. They default to availability: the model reasons that it has no record of finishing, so it tries again. A duplicate transaction is the result.
The answer is not a better prompt. It is an authoritative record the agent can query instead of guessing, plus an idempotency key that makes the retry safe even when the guess is wrong. AWS describes an idempotent operation as one where a request "can be retransmitted or retried with no additional side effects". It recommends that the caller send a unique client request token, which the service records in the same atomic step as the change it makes. Stripe's API works the same way: retries with the same key return the saved response instead of performing the operation twice.
Agentic systems inherit every classic distributed systems problem: partitions, stale state, duplicate messages, race conditions and partial transactions. Then they add a category of their own: non-deterministic reasoning, wrong tool selection, hallucination, context contamination and prompt injection. A retried network request can be made idempotent. A retried reasoning step may choose a completely different path. A production agent has to manage uncertainty in both execution and reasoning.
05The failure that is worse than a timeout
A timeout at least tells you something went wrong. Here is the version that does not.
The agent invokes a payment-like operation. The downstream system commits it. Microseconds later, the agent runtime crashes before it records that the step completed. Nothing looks broken. There was no error, no partition, no timeout. The business state is correct and the agent's state is simply missing.
If recovery asks the model to continue from what it remembers, the model attempts the payment again, confidently, because from its point of view the step never happened. Making the model smarter does not help. The model is not wrong. Its record is wrong, and no amount of reasoning can fix a fact that was never durably written down.
The fix is ordinary, unglamorous systems engineering: idempotency keys, durable workflow state, authoritative transaction records, reconciliation, transactional messaging and compensating actions. On recovery, the agent should ask whether operation 87423 actually committed, not reason that it does not remember finishing and should try again. That is the difference between agent memory and authoritative system state.
06CARE: a design lens for production agents
I use a simple mental model when designing production agentic systems. I call it CARE.
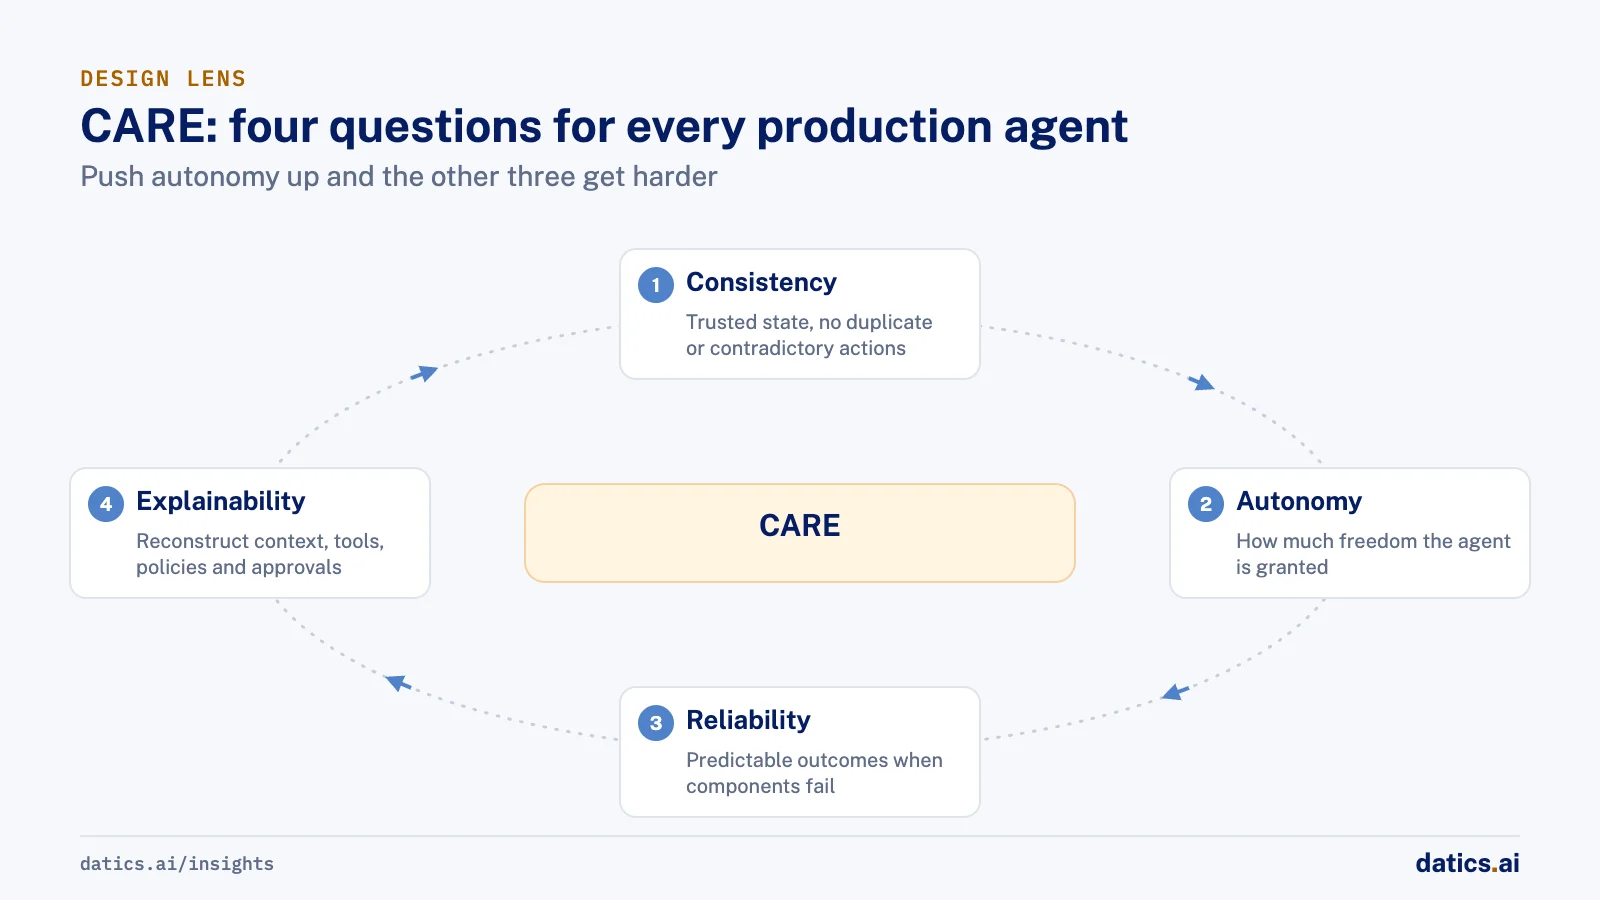
- Consistency. Can I trust the state, and prevent contradictory or duplicate actions?
- Autonomy. How much freedom am I actually granting this agent to reason, delegate and execute?
- Reliability. Can the workflow still produce a predictable business outcome when components fail?
- Explainability. Can I reconstruct the context, reasoning, tools, policies, approvals and resulting state change?
CARE is not a theorem, and it is not a replacement for CAP. It is a design lens that forces the right questions early. Push autonomy up, and consistency, reliability and explainability all get harder at once. That trade-off should be a deliberate architectural decision, not an accident of implementation.
07Authority has to rise with capability
Compare two sentences: "Based on these conditions, I recommend reviewing your exposure." And: "I have adjusted the portfolio." A few words apart in English. Worlds apart architecturally. The first produces information. The second changes enterprise state, and pulls identity, authorization, policy, idempotency, durable state, human approval, compensating actions, audit and blast radius into your AI architecture.
The control boundary has three layers. The probabilistic layer reasons, plans and selects tools. The deterministic layer applies identity, delegated authority, policy, approval, idempotency, transaction validation and audit. The enterprise action updates records, sends messages or executes transactions. The model can request an action. It should never be the component that authorizes it.
An agent should also not be handed a powerful service account just because it needs to talk to business systems. User identity, workload identity and delegated authority are three separate things. An agent may authenticate as a workload, but the effective permission for any action should still reflect the authority of the person or process it represents. OWASP makes the same point in its entry on excessive agency: run actions in the user's own context, and enforce authorization in the downstream system rather than relying on the model to decide.
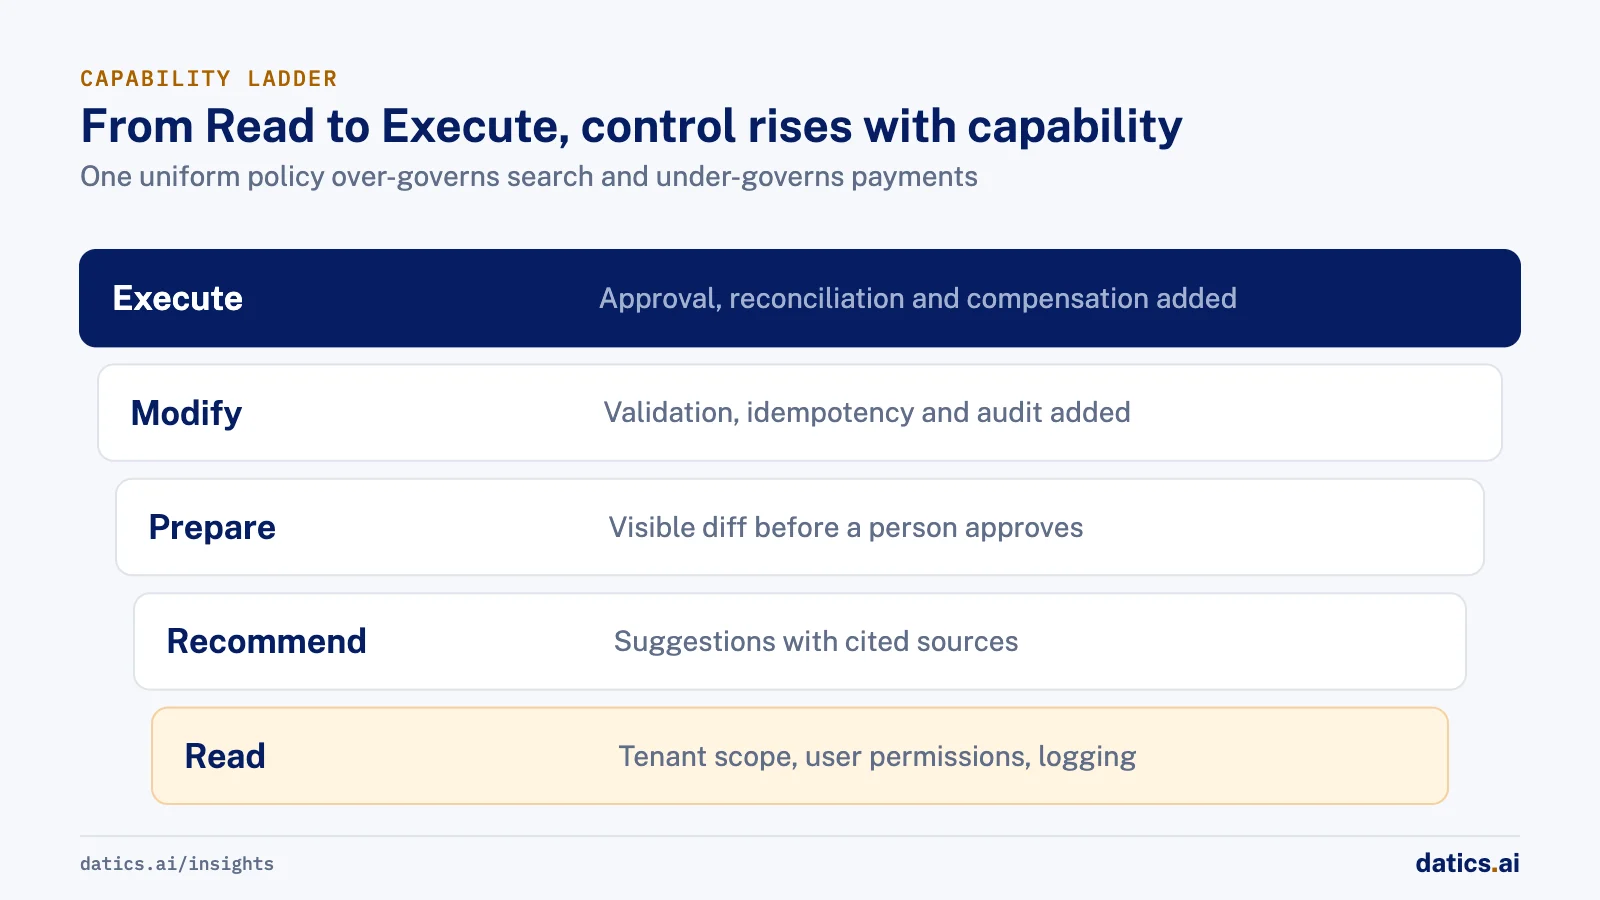
Not every tool deserves the same control. I think of agent capability as a ladder, from Read to Execute:
| Rung | What the agent does | Controls it needs |
|---|---|---|
| Read | Looks up records and documents | Tenant scope, user permissions, logging |
| Recommend | Suggests a next step | The above, plus cited sources |
| Prepare | Drafts a change for a person | The above, plus a visible diff before approval |
| Modify | Writes to a record | The above, plus validation, idempotency and audit |
| Execute | Moves money, sends, commits | The above, plus approval, reconciliation and compensation |
Most teams apply one uniform policy across the whole ladder. That is how you end up over-governing search and under-governing payments. An agent should never gain more authority simply because a model sits between the user and the system.
08What we see in production
At Datics, the work that decides whether an agent ships is rarely the model. It is what the agent may read, do and change in the product, and the same patterns come back across the established products we work in.
On a live property tax platform that changed owners, production support came before any restructuring, so every tax office kept collecting while the code moved to the new owner. On an investment administration platform, admins, investors and sub-clients have separated access, and AI-assisted onboarding and document work has to respect that separation on every call. On a governed AI verification platform, AI content is traced, classified, verified and audit-gated before publication. On WikiTeq's self hosted AI chat, retrieval runs as a separate service, and if it fails, the chat carries on as before. And on a race registration site nobody could support, we cloned production to a test site and rebuilt code that existed only in production before changing anything.
On a team AI chat product built on an old fork of an open source framework, we migrated every custom feature onto a current release before adding anything new. Each feature added to an outdated fork would have made the next upgrade harder.
None of those choices made the model smarter. All of them made the system trustworthy enough to put in front of real operations. For the product side of this, adding agents through your existing APIs and permissions, see how to add AI agents to an existing SaaS product.
09Five questions before an agent touches real operations
Models will get better. Agents will get more capable. Tool use will get more reliable. But as AI moves from answering to recommending to planning to acting, the architectural question changes: where does probabilistic reasoning end, and deterministic enterprise control begin?
- Can I trust the state this agent is acting on? Identify the authoritative system and how the agent confirms current state before acting.
- How much autonomy am I actually granting? Make the level of delegated freedom an explicit product and architecture decision.
- What happens when it fails halfway through? Design recovery, reconciliation and compensating actions before rollout.
- Can I reconstruct exactly what happened, months later? Retain the context, decision, policy, approval, tool call and resulting state change. For agentic systems, the trace becomes part of the evidence.
- Who really holds the authority to act? Keep identity, workload access and delegated user authority distinct.
If you cannot answer all five, you do not have a production system yet. You have a very good demo. The layer that lasts is not the model or the framework, which will keep changing. It is the layer around them: identity, authorization, state, tool contracts, policy, evaluation, observability, audit and data boundaries. The more autonomous AI becomes, the more distributed systems discipline it demands.
Frequently asked questions
How do idempotency keys stop duplicate payments?
The caller sends a unique client request token with the operation, and the service records it in the same atomic step as the change it makes. A retry with the same key returns the saved response instead of performing the operation twice. That makes the retry safe even when the agent guesses wrong about whether the first call committed.
Should an AI agent use a service account?
Not a powerful one just because it needs to talk to business systems. An agent may authenticate as a workload, but the effective permission for any action should still reflect the authority of the person or process it represents. Enforce authorization in the downstream system rather than relying on the model to decide.
Which agent actions need the most control?
The ones that change enterprise state. Reading records needs tenant scope, user permissions and logging. Modifying a record adds validation, idempotency and audit. Executing, such as moving money or sending messages, adds approval, reconciliation and compensation. One uniform policy across all of them over-governs search and under-governs payments.
How Datics helps
Datics specializes in Brownfield AI: production AI inside software people already rely on. A Build Sprint puts one outcome working in your product's staging in three weeks, for $10,000, and the fee counts toward production. Not sure what to build first? The Planning Sprint ranks it in two weeks, for $5,000.
Related work
Case studies from our projects on the same subject.
A European team AI chat provider
Other software · Multi-model team AI chat
Team AI chat moved onto current open source, every custom feature kept
A team AI chat product had its own features stuck on an outdated open source fork. We carried them onto a current base, open to more AI models.
SovrenAI
Other software · Atomic Builder, an AI website builder
Anyone describes a website in plain English and gets a deployed multipage site
Building a site took code or design skills; now a prompt produces a multipage site that is validated, fixed and previewed before deployment.
More on AI agents
AI agents
AI agents for business: add them to SaaS without a rebuild
AI agents for business work best inside the SaaS product you already run: your APIs as tools, your permissions as the boundary, human approval on writes.
 Umair MajeedRead
AI agents
Agent harness: run AI agents reliably in a SaaS app
An agent harness is the software around the model: tools, permissions, small steps, retries and human approval, so AI agents run safely inside a SaaS product.
 Rana Umar MajeedRead
AI agents
How do you manage AI agent memory in production?
AI agent memory in production is an infrastructure problem: durable checkpoints per thread, a pooled connection with reconnects, chat summaries and reset rules.
Rana Umar MajeedReadAI agents
Where should AI agent security enforce permissions?
AI agent security in a multi-role SaaS product rests on one rule: the agent gets the user's permissions and nothing more, enforced in code, never in the prompt.
Rana Umar MajeedReadAI agents
Which AI agent architecture fits a high-stakes workflow?
For a high-stakes workflow, the stronger AI agent architecture is a supervisor routing to narrow sub-agents, each with a contract and a human decision point.
Rana Umar MajeedReadAI agents
How much autonomy should AI agent guardrails allow?
AI agent guardrails that work: agents read and draft freely, but need consent and an editable confirmation before moving money, changing records or messaging.
Umair MajeedReadYour customers already expect AI from your product.
Let us make it real inside the product you run today.